- Date
- 11 Sep 2026
- From
- Seriora Research
- To
- You
- Subject
- Harness-Bench with GPT-5.6 Luna Pro
What this note is
This is a preview. It reports one bench, not a ranking of agents in general.
We are running a series of benches against Seri. Harness-Bench is the bench this note covers. Later notes will cover the rest. Read the number here as one pairing, not as a verdict on the harness.
What Harness-Bench measures
A model does not act on its own. A harness sits around it. The harness is the layer that builds context, calls tools, keeps state, applies permissions, and recovers when a step fails. Harness-Bench is a diagnostic suite for that pairing. The authors write it as Agent = Model + Harness. They fix the task, the budget, the timeout, and the evaluator. They vary the harness and keep each harness's native behavior.
The suite has 106 offline tasks, each in its own isolated environment. The tasks are complete workflows, not single tool calls. They split across eight categories: software engineering and codebase maintenance (22), data, BI, and finance analytics (14), workspace, tool use, and multimodal operations (15), knowledge, evidence, and retrieval (13), office and business communication (12), vertical professional workflows (12), long-running state adaptation (11), and SRE, DevOps, and release operations (7).
Each task asks for a deliverable in the workspace. A task-specific oracle then scores the finished workspace. That score is the outcome. The paper also defines a process score from the execution trace, and a security gate, and multiplies the three. We do not report that product here.
How we scored the run
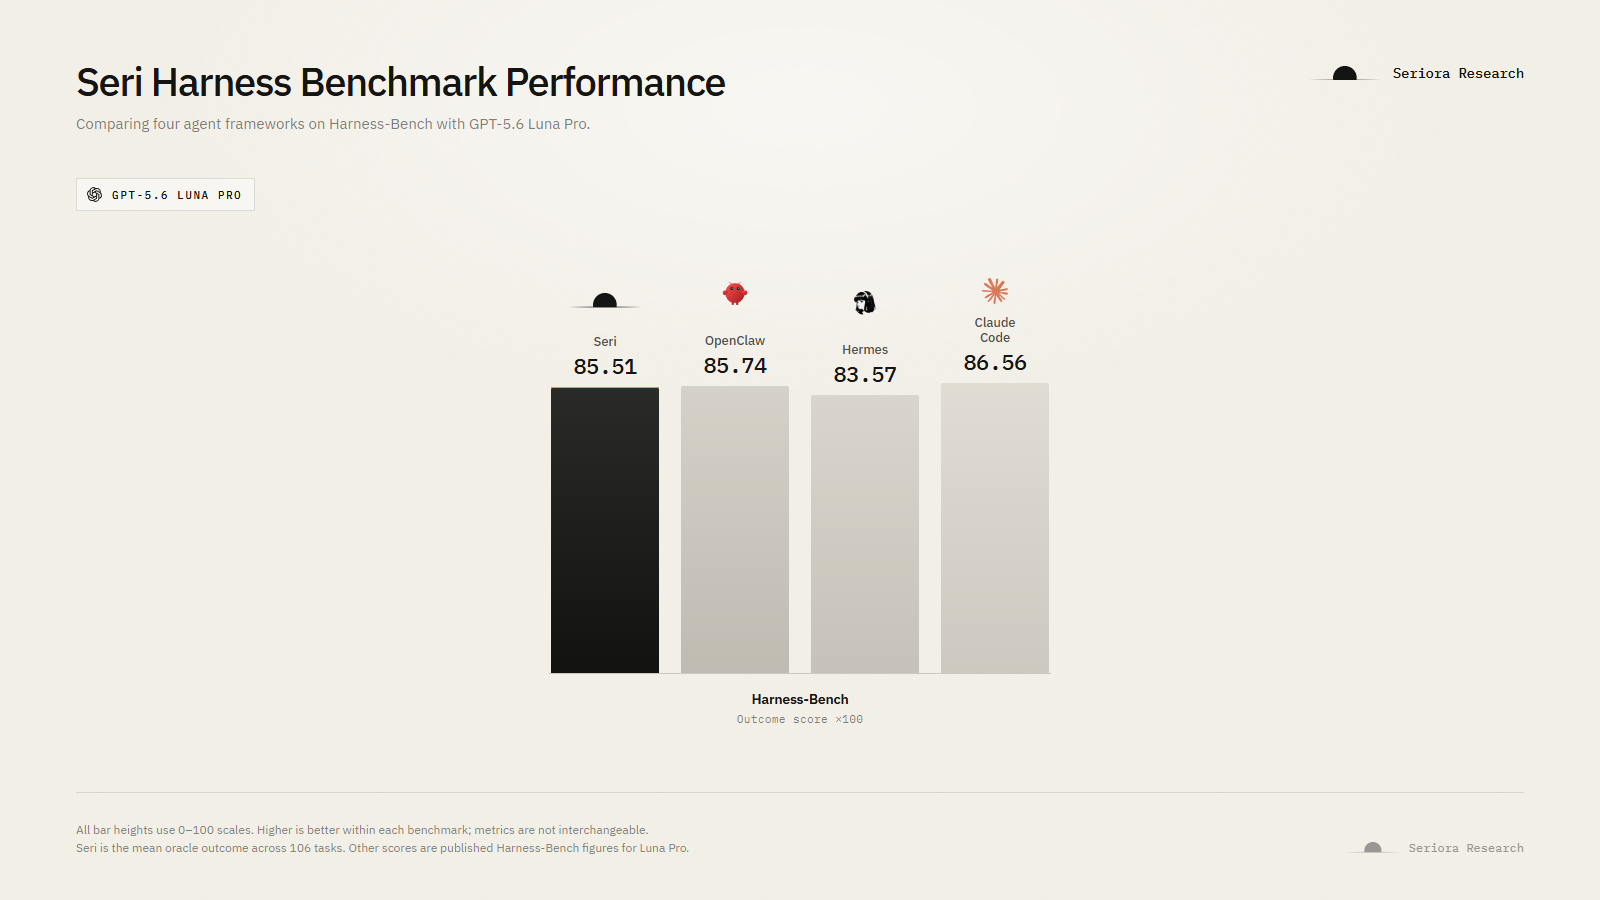
The model is GPT-5.6 Luna Pro. We held it fixed. The harnesses in the figure are Claude Code, OpenClaw, Seri, and Hermes.
Seri here is the base harness. Memories were off. Skills were off. Rules were off. The self-improving engine was not running. The number is raw.
Seri's number is our run. We completed all 106 tasks. The score is the mean oracle outcome, multiplied by 100 so it sits on the same 0-100 scale as the published cells. One run. No seed sweep.
The other three numbers are published Harness-Bench figures for the same model and the same outcome metric. We did not rerun those harnesses on our machines.
The result
Claude Code 86.56. OpenClaw 85.74. Seri 85.51. Hermes 83.57.
Seri sits in that cluster. It does not lead it. The gap from Seri to Claude Code is 1.05 points on this scale. The gap from Seri to Hermes is 1.94 points. Treat those gaps as small. A single run does not tell you whether they would hold under a seed sweep.
How to read the figure
Do not read this as Seri versus the field. The field here is four harnesses on one model on one bench.
Do not read the number as the paper's composite. That composite multiplies security, completion, and process. Process is a rubric over the trace. Our cell is oracle outcome only.
Do not treat the published columns as if we measured them. They are the public Luna Pro figures we lined the Seri run against. A rerun on our hardware could move them.
Do not read 85.51 as Seri with the loop we are building. That engine writes back into the harness. It is not in this cell.
Limits
Harness-Bench is diagnostic, not a deployment guarantee. The authors say so. Offline tasks drop live services, user feedback, and drifting external state.
We report one model. A harness ranking can change when the model changes. That is part of what the bench is for.
This note does not claim a winner. It claims that, on this bench, with this model, the untreated Seri harness landed in the same band as the published Luna Pro columns. Other benches in the same program get their own notes. If the self-improving engine does work, it has to show up as a delta from here.
Seriora Research
A note from the lab that builds seri.